 Genbaz
Rapidly generate 3D models from images using Hunyuan 3D.

High-fidelity mask-based video object removal with strong temporal consistency. Erase unwanted objects, people, or elements while preserving aesthetic quality. Trained on licensed data for risk-free commercial use.

LoRA inference endpoint for Qwen Image 2512, an improved version of Qwen Image with better text rendering, finer natural textures, and more realistic human generation.
Recraft V4 was developed with designers to bring true visual taste to AI image generation. Built for brand systems and production-ready workflows, it goes beyond prompt accuracy — delivering stronger composition, refined lighting, realistic materials, and a cohesive aesthetic. The result is imagery

Run SDXL at the speed of light
Happy Horse 1.1 is Alibaba's #1-ranked video model. This image-to-video endpoint animates a still image into 1080p video with synchronized native audio and multilingual lip-sync

Image-to-image editing with LoRA support for FLUX.2 [klein] 9B Base from Black Forest Labs. Specialized style transfer and domain-specific modifications.
Vidu Q4 turns a first-frame image into 3 to 16 second videos with native audio at up to 4K. Best for animating stills, product shots and character scenes with dialogue.

Kling 3.0 Turbo Standard is a fast, cost-efficient video generation model that turns text prompts directly into 720P video with native audio, optimized for rapid iteration and high-volume production
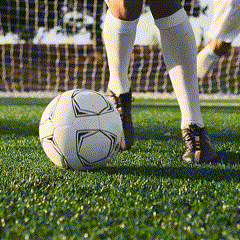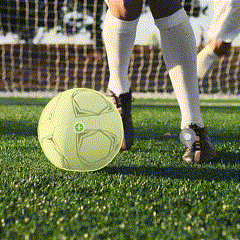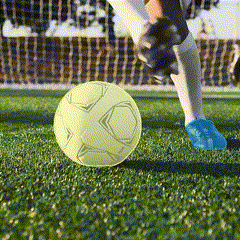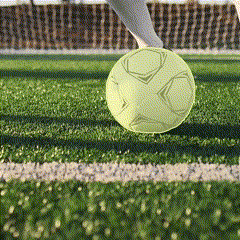
SAM 2 is a model for segmenting images and videos in real-time.
 ✦ new
HeyGen Voice Turbo is the fast, low-cost tier of HeyGen Voice, with library voices and instant cloning from a reference clip.

Generate 3D models from text prompts with Hunyuan 3D Pro

MAI-Image-2.5 is Microsoft's photorealistic image generation and editing model that turns text prompts or uploaded images into high-quality, design-ready visuals with fine-grained, pixel-level control.
US hosted version of ByteDance's most advanced image-to-video model. Animate still images into cinematic video with synchronized audio, start and end frame control, and motion prompts.

Seed Speech developed by ByteDance, is a family of large-scale text-to-speech models capable of synthesizing speech that is virtually indistinguishable from human speech.
Stable Audio 3 Small Music is a 459 million parameter latent diffusion model that generates full stereo music compositions up to 2 minutes from text prompts, lightweight enough for on-device deployment.

Finegrain Eraser removes any object selected with a mask—along with its shadows, reflections, and lighting artifacts—seamlessly reconstructing the scene with contextually accurate content.

LTX-2.5 is Lightricks' open-source audio-video model. This endpoint generates synchronized video and audio from a text prompt in a single pass, in a speed-optimized mode built for rapid iteration and previews.
FLUX.1 Krea [dev] is a 12 billion parameter flow transformer that generates high-quality images from text with incredible aesthetics. It is suitable for personal and commercial use.

Automatically remove backgrounds from videos -perfect for creating clean, professional content without a green screen.

Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

LTX-2.5 is Lightricks' open-source audio-video model. This endpoint generates synchronized video and audio from a text prompt in a single pass, in a quality-optimized mode for final, high-fidelity output.

Place any product in any scenery with just a prompt or reference image while maintaining high integrity of the product. Trained exclusively on licensed data for safe and risk-free commercial use and optimized for eCommerce.
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks