 Genbaz
Gemini 3.1 Flash Image (a.k.a Nano Banana 2) is Google's new state-of-the-art fast image generation and editing model
Moondream 3 is a vision language model that brings frontier-level visual reasoning with native object detection, pointing, and OCR capabilities to real-world applications requiring fast, inexpensive inference at scale.

Create stunningly realistic sound effects in seconds - CassetteAI's Sound Effects Model generates high-quality SFX up to 30 seconds long in just 1 second of processing time

FFMPEG Untility for Extracting nth Frame

Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Generate complete seamlessly tiling PBR materials including normal, roughness, basecolor, height and metalness maps up to 8K

FLUX LoRA Image-to-Image is a high-performance endpoint that transforms existing images using FLUX models, leveraging LoRA adaptations to enable rapid and precise image style transfer, modifications, and artistic variations.

Analyzes your video’s pacing, mood, and timing to generate a frame-synced, licensed, commercial-use-safe soundtrack in seconds.
 ✦ new
Gemini Omni Flash 1.2 is Google's multimodal video model. This endpoint edits an existing video of up to 15 seconds from a natural-language instruction, applying the requested change while keeping the rest of the scene unchanged. Output resolution is selectable from 360p, 720p, 1080p, or 4K.
Remove background from any video with people and objects. No green screen needed.
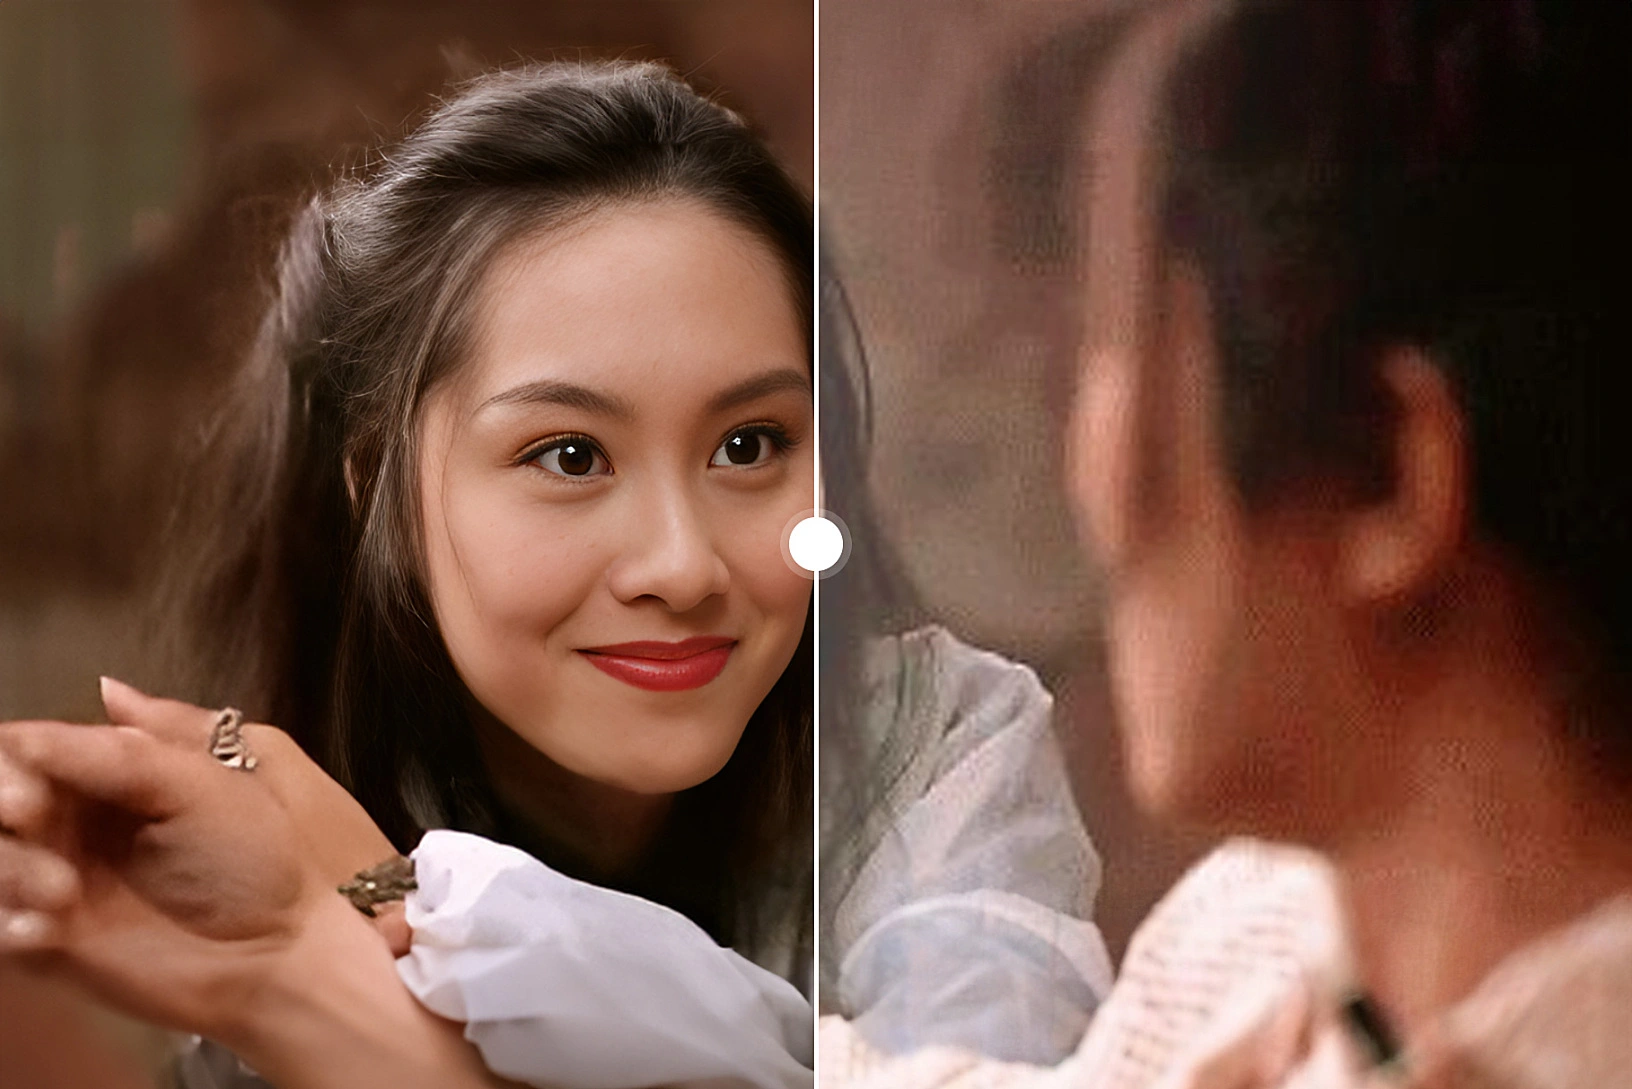
Fix distorted or blurred photos of people with CodeFormer.
 ✦ new
Generates editable SVG vector graphics from text prompts, with optional reference images, three quality levels, and aspect ratio controls.
Merge audios into a single audio using FFmpeg API!

Kling O3 Omni generates new shots guided by an input reference video, preserving cinematic language such as motion, and camera style to produce seamless scene continuity.

Text-to-image generation with LoRA support for FLUX.2 [dev] from Black Forest Labs. Custom style adaptation and fine-tuned model variations.

Directional outpainting. Choose edges to expand. left, right, top, or center (uniform all sides). Only expanded areas are generated; an optional zoom-out pulls the frame back by the chosen amount.

Generate natural, clear speeches using Index TTS 2.0 from IndexTeam
Luma Ray 3.2 animates a source image into cinematic motion guided by a text prompt, preserving the starting frame's look while controlling resolution, duration, and seamless looping.

Professional creative image upscaling powered by Topaz Labs. Bloom 2 reinvents detail with adjustable creativity and color preservation. Best for AI-generated images that need striking enhancement.
 ✦ new
Generate images fast with distilled FLUX 3 Image Klein and up to 3 custom LoRAs.
Generate videos from text prompts using xAI's Grok Imagine Video 1.5 Lite model.

Image editing with FLUX.2 [flex] from Black Forest Labs. Supports multi-reference editing with customizable inference steps and enhanced text rendering.

Wan 2.7 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
Generates songs from a text prompt or supplied lyrics, with musical style, vocal, reference-audio, and melody controls, plus support for multiple variations.