 Genbaz
Moondream 3 is a vision language model that brings frontier-level visual reasoning with native object detection, pointing, and OCR capabilities to real-world applications requiring fast, inexpensive inference at scale.

Create depth maps using Midas depth estimation.

Use SeedVR2 to upscale images, retaining seamless tiling

Endpoint for Qwen's Image Editing 2511 model with LoRa support.

Image-to-image editing with LoRA support for FLUX.2 [dev] from Black Forest Labs. Specialized style transfer and domain-specific modifications.
Edit and transform images using text instructions with the WAN 2.7 Pro model for precise, professional-grade image modifications.
 ✦ new
Converts images into editable SVG vector graphics, with a default mode for finer details and a simple mode for fewer shapes.
Upscale any image 2x or 4x, up to 8192×8192, with Bria Increase Resolution. Preserves the original content — no regeneration, no altered details. Commercial-safe
 ✦ new
Background removal you steer with a prompt. Starts from the same clean cut as Bria RMBG, then adds, drops or isolates objects from plain words like "the person with the mat and the plant" or "only the chair". Original pixels, real alpha, nothing repainted.

Bria Background Replace allows for efficient swapping of backgrounds in images via text prompts or reference image, delivering realistic and polished results. Trained exclusively on licensed data for safe and risk-free commercial use

Removes mask-selected objects and their visual effects, seamlessly reconstructing the scene with contextually appropriate content.
FLUX LoRA training optimized for portrait generation, with bright highlights, excellent prompt following and highly detailed results.

Professional transparent-image upscaling powered by Topaz Labs. Preserves the alpha channel end to end with PNG output. Best for logos, stickers and assets with transparency.

Inpainting Endpoint for the Qwen Edit Image editing model.
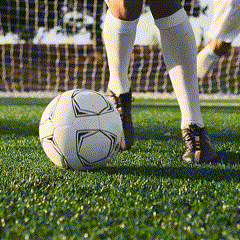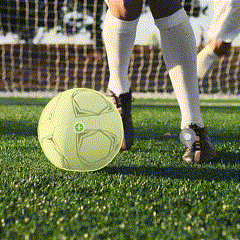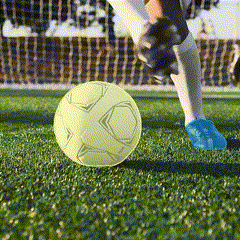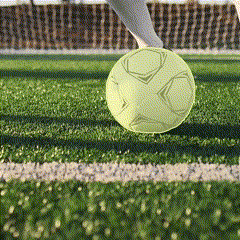
SAM 2 is a model for segmenting images automatically. It can return individual masks or a single mask for the entire image.
 ✦ new
Edit images fast with distilled FLUX 3 Image Klein and up to 3 custom LoRAs.

Image-to-image editing with LoRA support for FLUX.2 [klein] 9B Base from Black Forest Labs. Specialized style transfer and domain-specific modifications.

MAI-Image-2.5 is Microsoft's photorealistic image generation and editing model that turns text prompts or uploaded images into high-quality, design-ready visuals with fine-grained, pixel-level control.

Finegrain Eraser removes any object selected with a mask—along with its shadows, reflections, and lighting artifacts—seamlessly reconstructing the scene with contextually accurate content.

Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Place any product in any scenery with just a prompt or reference image while maintaining high integrity of the product. Trained exclusively on licensed data for safe and risk-free commercial use and optimized for eCommerce.
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

FLUX General Image-to-Image is a versatile endpoint that transforms existing images with support for LoRA, ControlNet, and IP-Adapter extensions, enabling precise control over style transfer, modifications, and artistic variations through multiple guidance methods.
Bria Virtual Try-On edits a person photo to show the subject wearing garments or accessories from one to three reference images, guided by optional text instructions. Built on FIBO-Edit-1.5, it supports multi-garment changes and preserves the source aspect ratio by default.