 Genbaz

Luma Ray 3.2 generates cinematic video from a text prompt, with control over resolution, duration, and seamless looping, plus reference images to lock in subject and style.

Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.
Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.
Wan 2.6 text-to-video model.

Happy Horse 1.1 is Alibaba's #1-ranked video model. This text-to-video endpoint generates 1080p video with synchronized native audio and multilingual lip-sync from a text prompt alone.
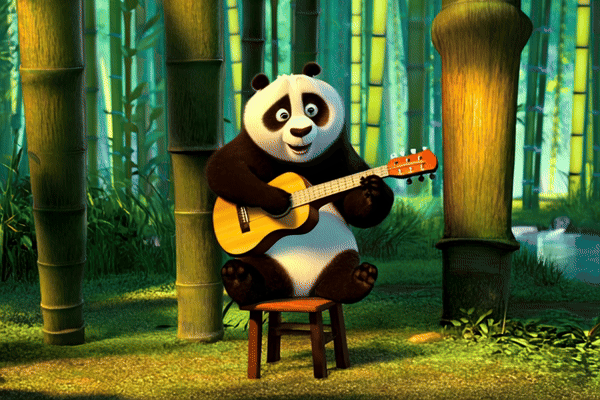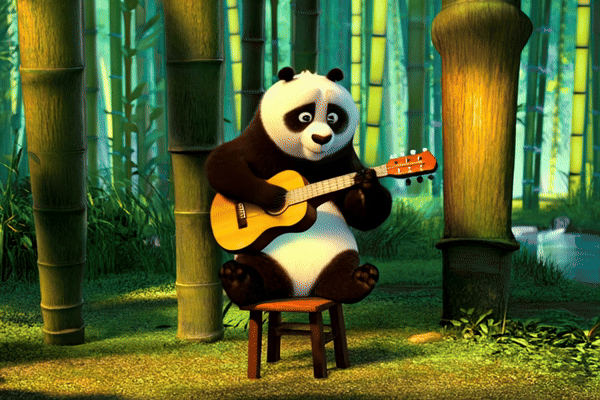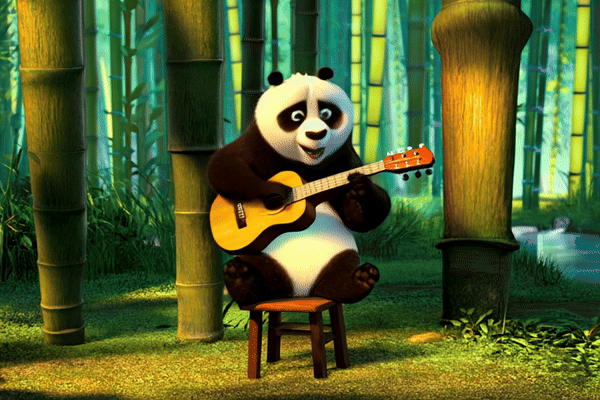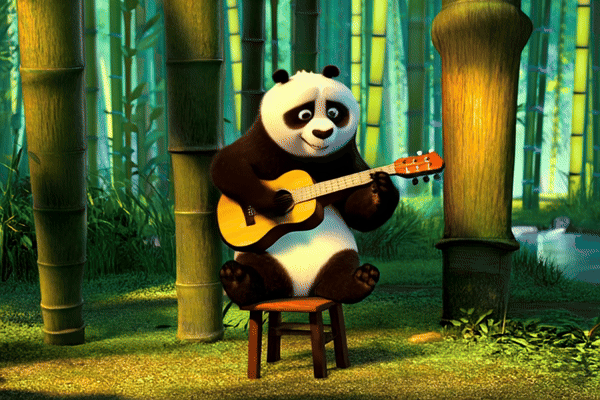
Generate videos from prompts using LTX Video 0.9.1

Generate 1080p video with synchronized native audio from a text prompt. Aspect ratios: 16:9, 9:16, 1:1, 4:3, 3:4. Duration: 3–15s.
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Vidu's latest Q3 pro models
US hosted version of ByteDance's most advanced text-to-video model. Cinematic output with native audio, multi-shot editing, real-world physics, and director-level camera control.

FLUX.3 is Black Forest Labs' frontier audio/video model. Generate fast, low-cost draft previews from a text prompt, with a reusable draft cache for full-quality enhancement.
Generate high quality video clips from text and image prompts using PixVerse v5

MoonDreamNext is a multimodal vision-language model for captioning, gaze detection, bbox detection, point detection, and more.

Generate video clips from your prompts using MiniMax model
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
Moondream 3 is a vision language model that brings frontier-level visual reasoning with native object detection, pointing, and OCR capabilities to real-world applications requiring fast, inexpensive inference at scale.

MiniMax Hailuo-2.3 Text To Video API (Pro, 1080p): Advanced text-to-video generation model with 1080p resolution
Generate film-grade videos from text prompts with native audio, up to 1080p and 15 seconds, using PixVerse C1.
Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.
Moondream 3 is a vision language model that brings frontier-level visual reasoning with native object detection, pointing, and OCR capabilities to real-world applications requiring fast, inexpensive inference at scale.
Vidu's Q3 Turbo Model.

Generate videos from prompts using LTX Video-0.9.7 13B Distilled and custom LoRA

Generate video clips from your prompts using MiniMax model