 Genbaz
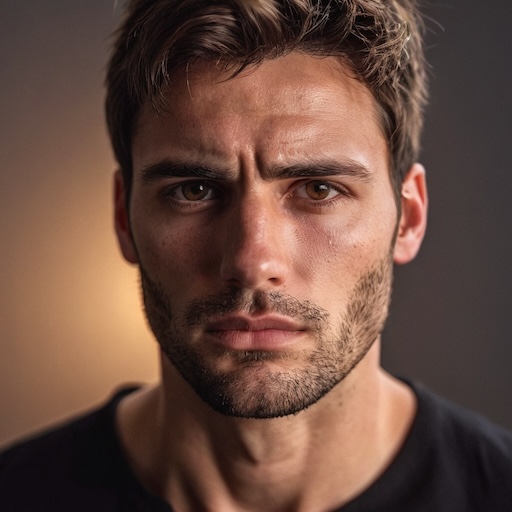
Transfer expression from a video to a portrait.

A fast and high quality model for image background removal.
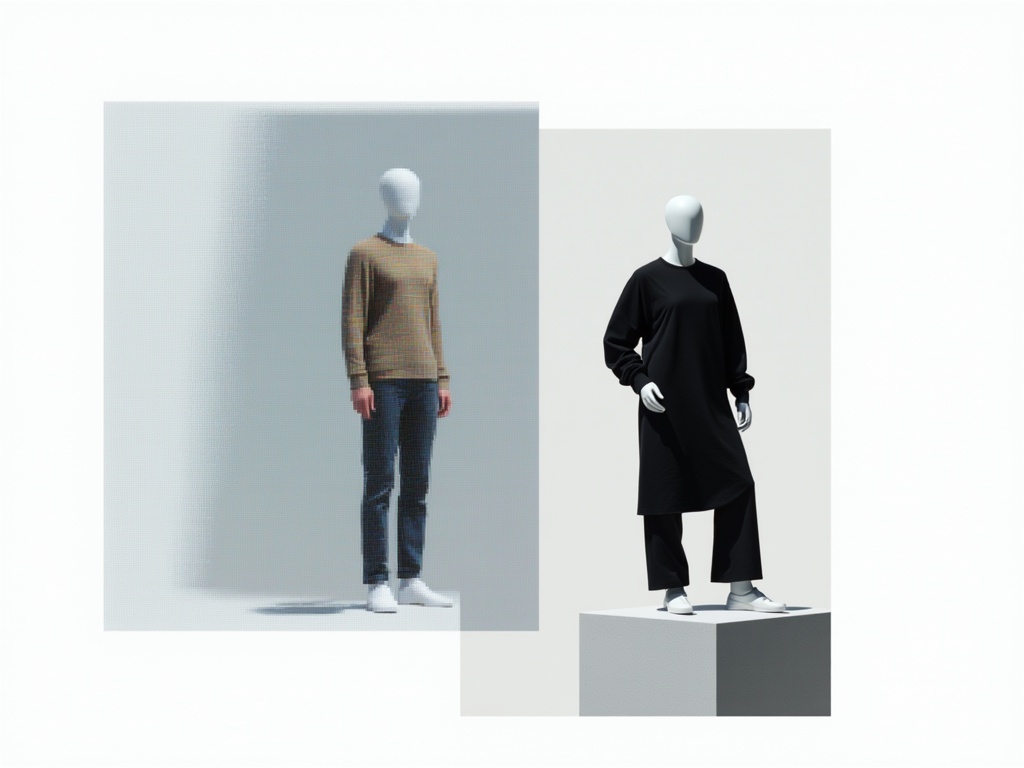
Image editing with HY-WU. Transfer outfits, swap faces, and blend textures instantly—no finetuning needed, just describe what you want and provide reference images.

SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.

Luma Uni-1 Max Edit applies text-guided edits to a source image at maximum fidelity, holding the original structure while honoring reference images for precise, high-detail revisions.

Generate images from text and edge, depth or pose images using Z-Image Turbo, Tongyi-MAI's super-fast 6B model.
Estimate depth from a single image with Marigold V2, a diffusion-based depth model built on Qwen-Image-Edit, returning a colorized depth map.

Generate images from text and images using custom LoRA and Z-Image Turbo, Tongyi-MAI's super-fast 6B model.

Modify consistent characters while preserving their core identity. Edit poses, expressions, or clothing without losing recognizable character features

Reimagine existing images with Ideogram V3's remix feature. Create variations and adaptations while preserving core elements and adding new creative directions through prompt guidance.
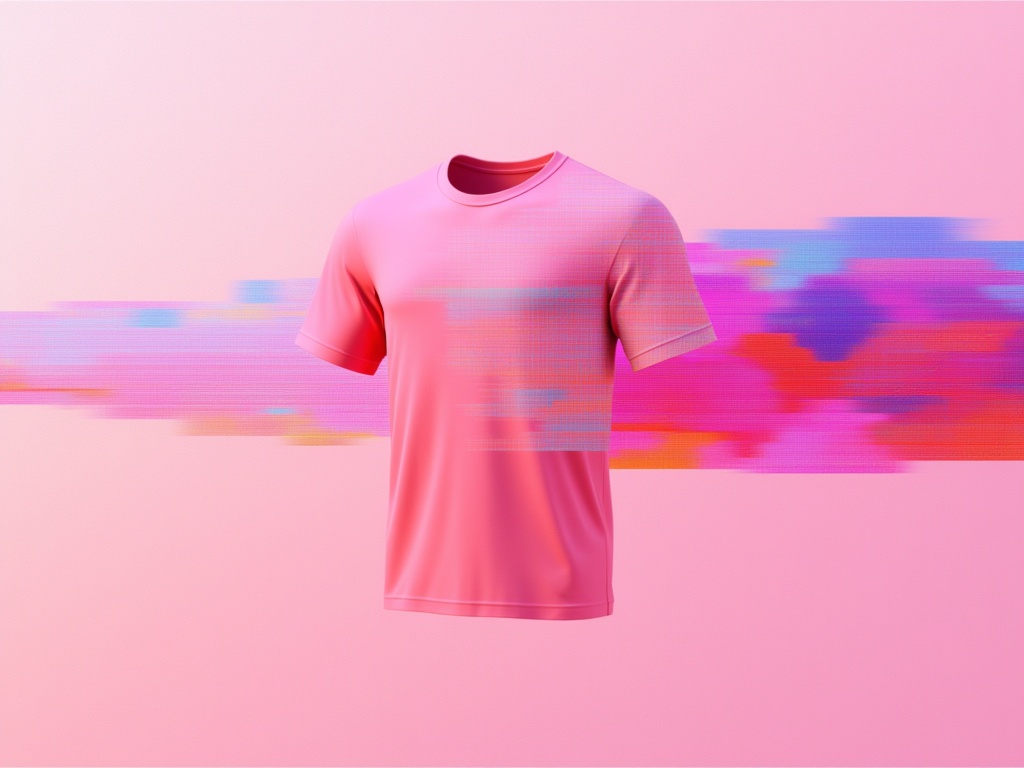
Generate realistic virtual try-on images from a person image and a clothing product image.

Restore old or damaged photos by fixing colors, scratches, and resolution.
Phota's model enables personalized photo editing, preserving identity while erasing distractions seamlessly.
The reframe endpoint intelligently adjusts an image's aspect ratio while preserving the main subject's position, composition, pose, and perspective

Luma Uni-1 Edit reworks a source image from a text instruction, preserving the original composition while applying style changes and following optional reference images to steer the result.
Remove all text and writing from images while preserving the background and natural appearance.

Image2SVG transforms raster images into clean vector graphics, preserving visual quality while enabling scalable, customizable SVG outputs with precise control over detail levels.

Create creative upscaled images.
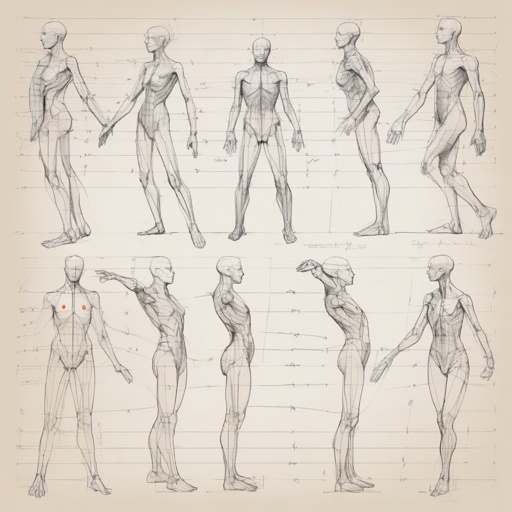
Predict poses from images.

Bria GenFill enables high-quality object addition or visual transformation. Trained exclusively on licensed data for safe and risk-free commercial use. Access the model's source code and weights: https://bria.ai/contact-us

Hunyuan World 1.0 turns a single image into a panorama or a 3D world. It creates realistic scenes from the image, allowing you to explore and view it from different angles.

Fast inpainting endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image inpainting with reference images, while using pre-trained LoRA adaptations for specific styles, brand identities, and product-specific outputs.

Image-to-image editing with FLUX.2 [klein] 4B Base from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.

Qwen-Image (Image-to-Image) transforms and edits input images with high fidelity, enabling precise style transfer, enhancement, and creative modification.