 Genbaz

Recraft V3 is a text-to-image model with the ability to generate long texts, vector art, images in brand style, and much more. As of today, it is SOTA in image generation, proven by Hugging Face's industry-leading Text-to-Image Benchmark by Artificial Analysis.
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.

Bria Extract Object uses text prompts to isolate a selected object from an image and return it as an RGBA PNG with a transparent background. Ideal for product, ecommerce, advertising, and creative editing workflows. Bria's Extract Object API leads in product shot extraction, outperforming SAM 3.1 wh

Generate virtual try-on results from a person image plus one or more garment references.
Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.

Image-to-image editing with Flux 2 [klein] 9B Base from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.
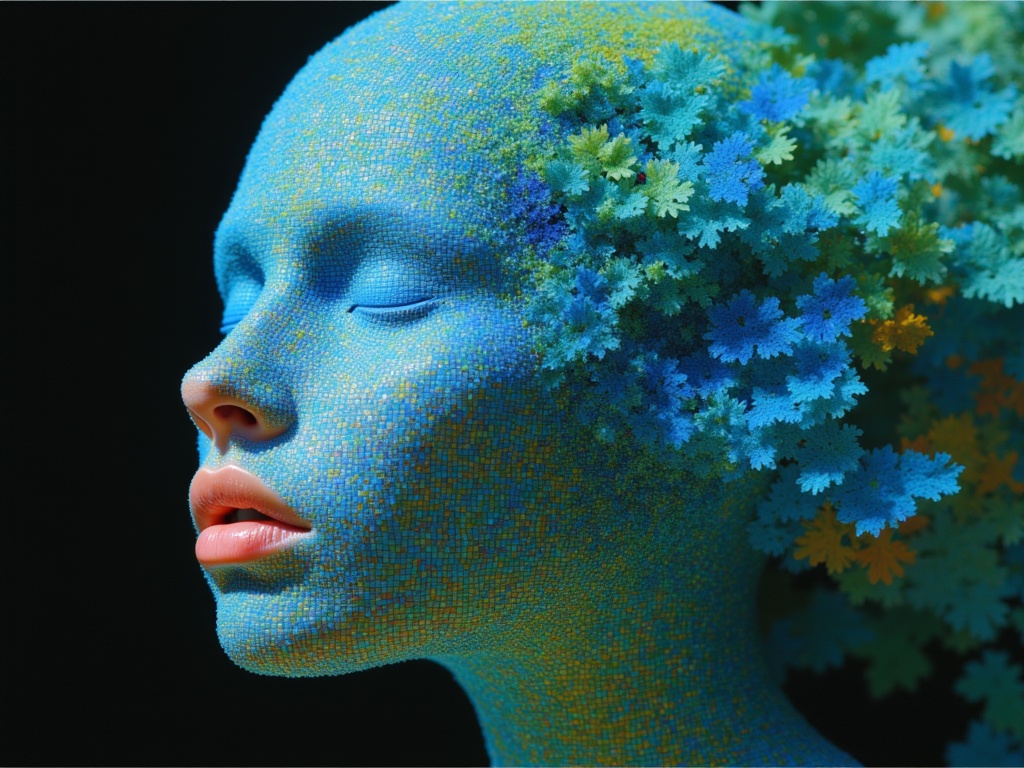
Ideogram V4.0q Image-to-Image transforms an input image with a text prompt, restyling and reworking the composition while preserving its core structure for prompt-faithful, high-fidelity edits.

Precise camera position and angle control (rotation, zoom, vertical movement)
Transfer expression from a video to a portrait.

A fast and high quality model for image background removal.
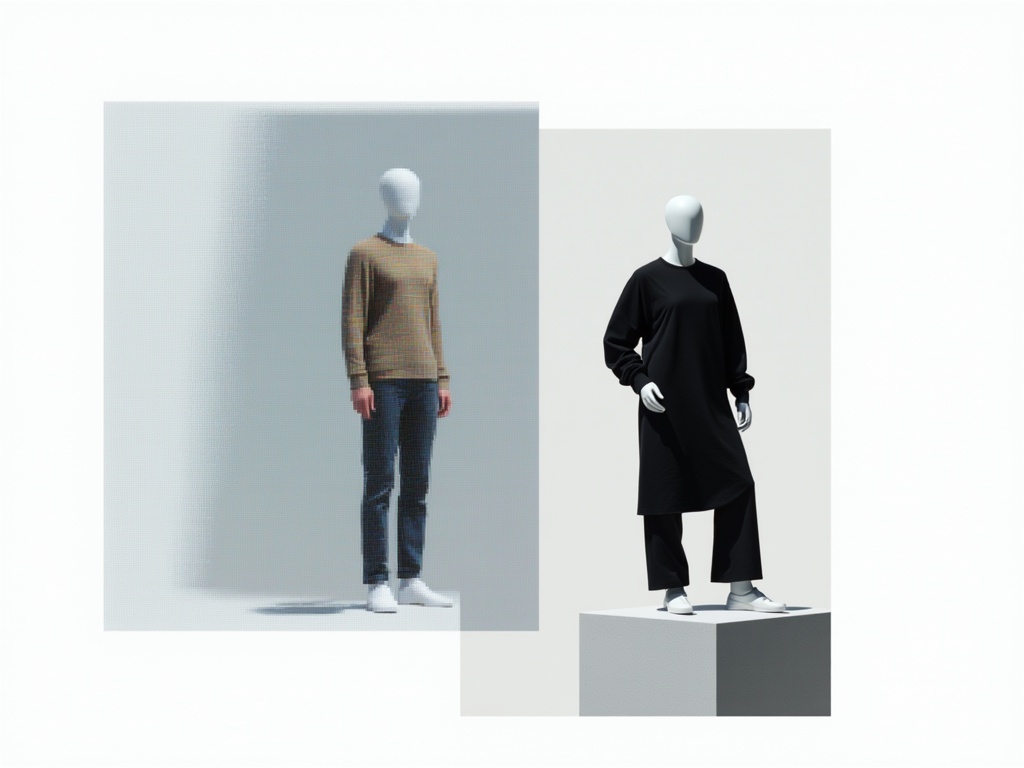
Image editing with HY-WU. Transfer outfits, swap faces, and blend textures instantly—no finetuning needed, just describe what you want and provide reference images.

SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.

Luma Uni-1 Max Edit applies text-guided edits to a source image at maximum fidelity, holding the original structure while honoring reference images for precise, high-detail revisions.

Generate images from text and edge, depth or pose images using Z-Image Turbo, Tongyi-MAI's super-fast 6B model.
Estimate depth from a single image with Marigold V2, a diffusion-based depth model built on Qwen-Image-Edit, returning a colorized depth map.

Generate images from text and images using custom LoRA and Z-Image Turbo, Tongyi-MAI's super-fast 6B model.

Modify consistent characters while preserving their core identity. Edit poses, expressions, or clothing without losing recognizable character features

Reimagine existing images with Ideogram V3's remix feature. Create variations and adaptations while preserving core elements and adding new creative directions through prompt guidance.
Generate realistic virtual try-on images from a person image and a clothing product image.
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks

Restore old or damaged photos by fixing colors, scratches, and resolution.
Phota's model enables personalized photo editing, preserving identity while erasing distractions seamlessly.
The reframe endpoint intelligently adjusts an image's aspect ratio while preserving the main subject's position, composition, pose, and perspective