 Genbaz

FLUX.1 SRPO [dev] is a 12 billion parameter flow transformer that generates high-quality images from text with incredible aesthetics. It is suitable for personal and commercial use.

Ballpoint pen sketch drawing style
ffmpeg utility to interleave videos

Default parameters with automated optimizations and quality improvements.

HDR surrealistic effect with intense colors

FLUX1.1 [pro] ultra fine-tuned is the newest version of FLUX1.1 [pro] with a fine-tuned LoRA, maintaining professional-grade image quality while delivering up to 2K resolution with improved photo realism.
Fine-tune FLUX.2 [dev] from Black Forest Labs with custom datasets. Create specialized LoRA adaptations for specific editing tasks.
Fine-tune FLUX.2 [dev] from Black Forest Labs with custom datasets. Create specialized LoRA adaptations for specific editing tasks.
Fine-tune LTX 2.3 to animate a starting image — supply a still plus a prompt at inference and the model generates a video that begins from that frame.
Train a MiniMax H3 LoRA with first-frame conditioning, so a still image animates into video with audio; captions optional.
Creates a reusable style from your reference images for use with Recraft V4 Styles Pro generation

Bria's Text-to-Image model with perfect harmony of latency and quality. Trained exclusively on licensed data for safe and risk-free commercial use. Available also as source code and weights. For access to weights: https://bria.ai/contact-us

Bria's Text-to-Image model for HD images. Trained exclusively on licensed data for safe and risk-free commercial use. Available also as source code and weights. For access to weights: https://bria.ai/contact-us

Generates satellite/aerial view style images

Applies sepia vintage effect to images
A preview to the next level of control of Text-to-Image models.
LoRA trainer for Qwen Image Edit 2509

High-quality text-to-image model by Baidu. Supports English, Chinese, and Japanese prompts with built-in prompt expansion.
Train a MiniMax H3 LoRA on your own captioned clips for pure text-to-video generation with matching audio.

High-quality text-to-image model by Baidu. Supports English, Chinese, and Japanese prompts with built-in prompt expansion.
Train a MiniMax H3 LoRA on first/last/both keyframe signatures, teaching it to generate video with audio that starts on one image and lands on another.
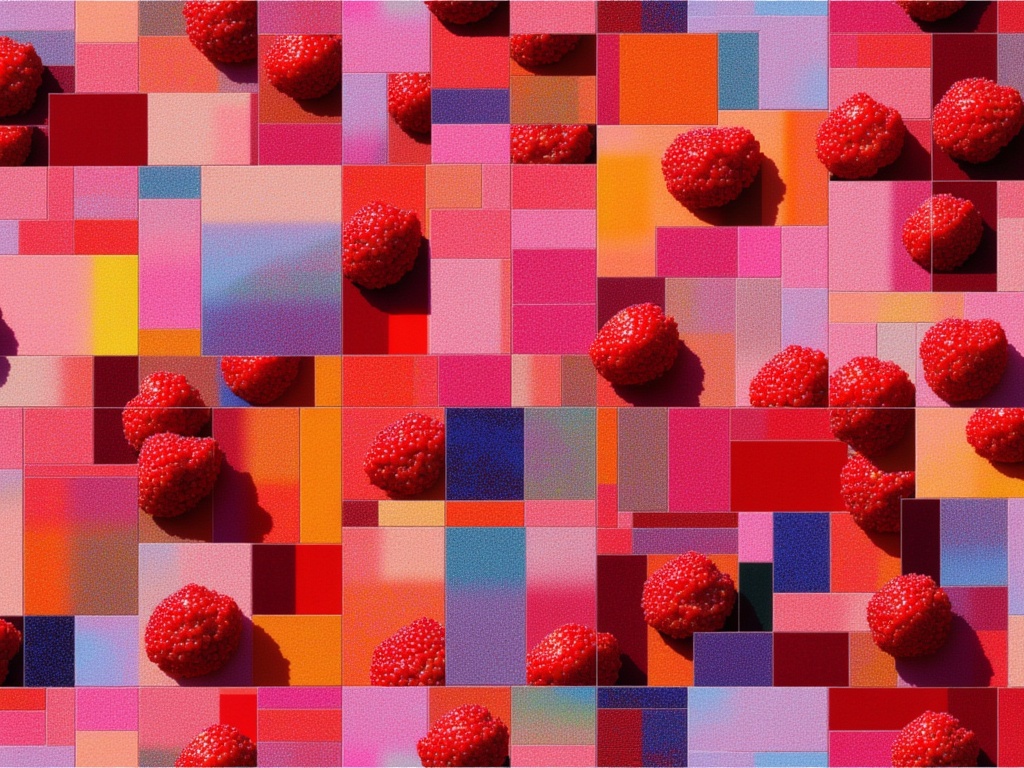
Generate seamlessly tiling photorealistic images from text using Z-Image Turbo and custom LoRA
Default parameters with automated optimizations and quality improvements.

Super fast endpoint for the FLUX.1 [dev] model with LoRA support, enabling rapid and high-quality image generation using pre-trained LoRA adaptations for personalization, specific styles, brand identities, and product-specific outputs.